Trace native behavior
Collect execution records without replacing native context policies, tool transport, or session behavior.
TRACELITE AI / RESEARCH
arXiv preprint · arXiv:2610.32285v1 ·
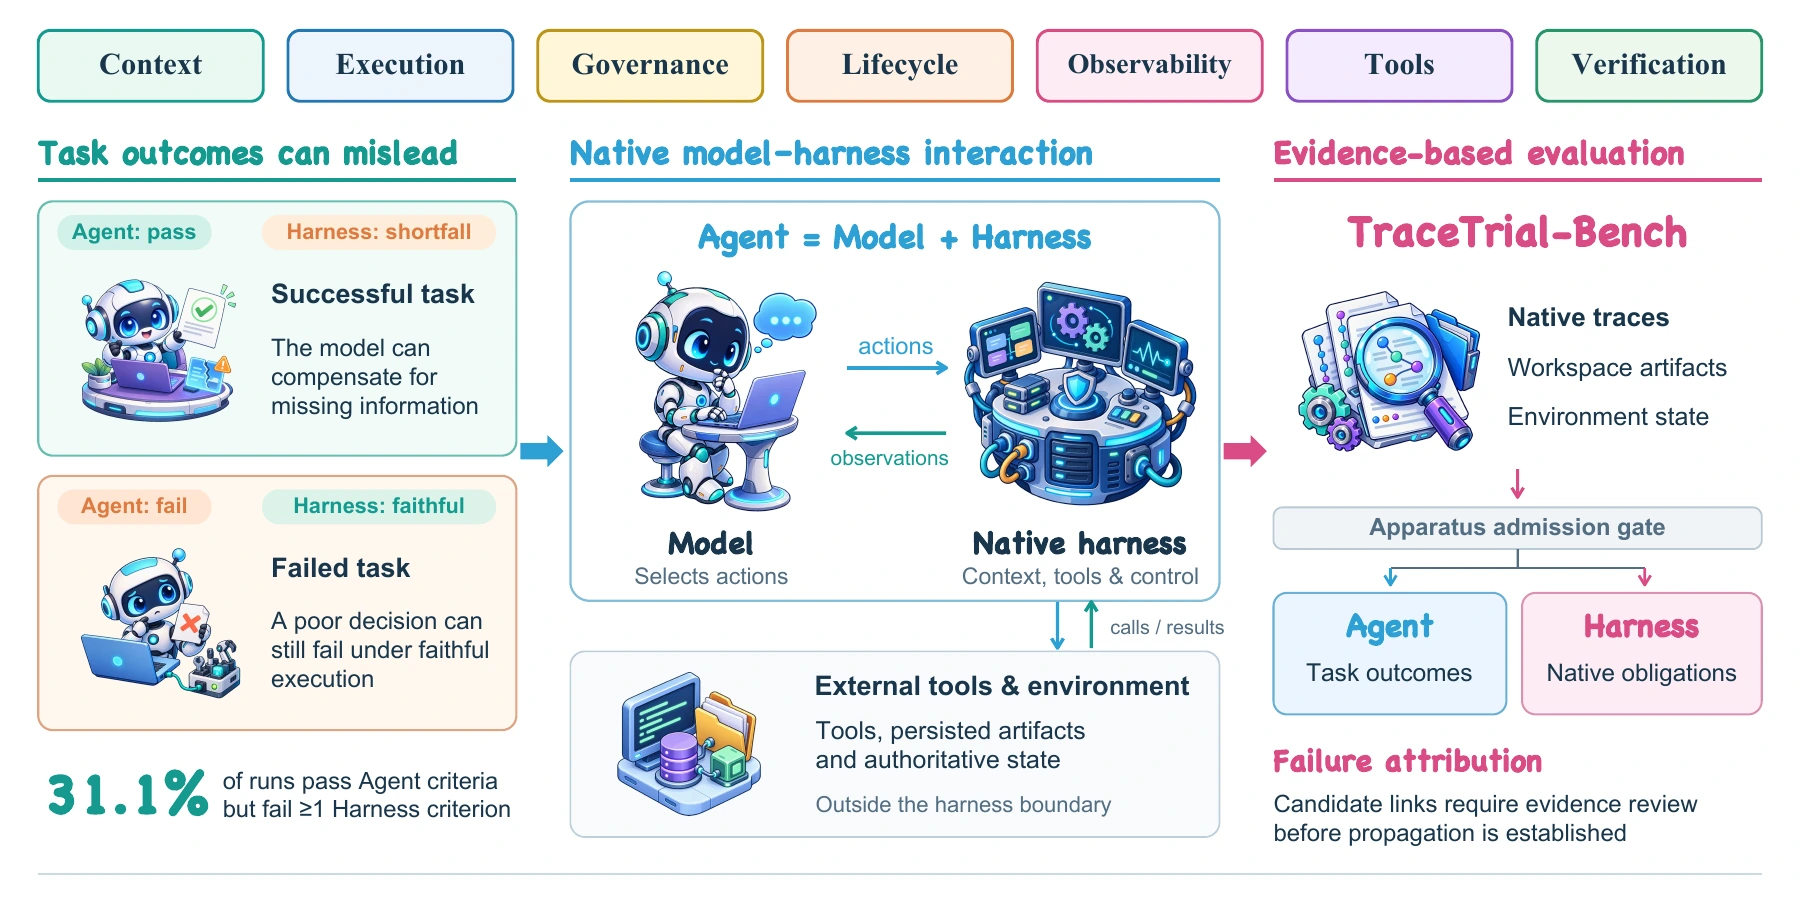
A successful task does not always mean a reliable harness.
LLM agents are increasingly used to solve real-world problems, and their effectiveness depends on both the underlying models and the harnesses that support their operation. However, most existing benchmarks focus on model capabilities and overall agent performance, with limited attention to the evaluation of agent harnesses.
To address this gap, we introduce TraceTrial-Bench, which organizes harness reliability into seven components covering context, execution, governance, lifecycle, observability, tools, and verification. We construct 95 expert-level, mechanism-oriented tasks with executable or state-based ground truth to support semantically equivalent comparisons while preserving the native behavior of each harness.
We design a Trajectory Tracing (TT) module to capture agent execution traces and introduce a two-layer evaluation framework that separately assesses agent performance and harness reliability. In addition, we design a Multi-source Evidence Acquisition (MEA) module to provide evidence from the agent context, harness, and execution environment for LLM-based evaluation, and develop a Failure Attribution (FA) module that uses explicit mechanism chains to support attribution at the run level.
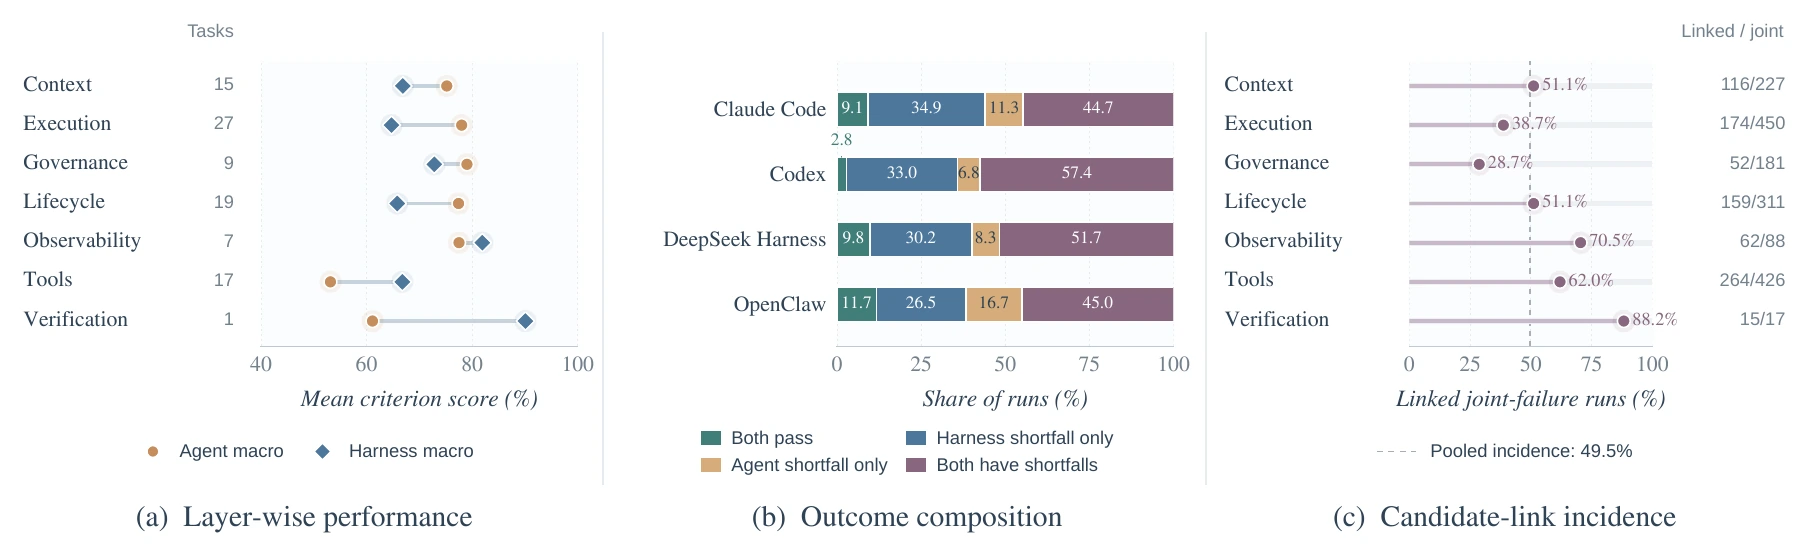
Across 4 harnesses, 9 models, and 95 tasks, our evaluation of 3,420 runs yields macro-averaged harness scores ranging from 59.8% to 72.0%, while 31.1% of runs achieve task success despite failing at least one harness criterion. TraceTrial-Bench provides an auditable and reproducible foundation for comparing agent harnesses, diagnosing their failures, and studying how harness design interacts with model behavior.
A benchmark for the system around the model.
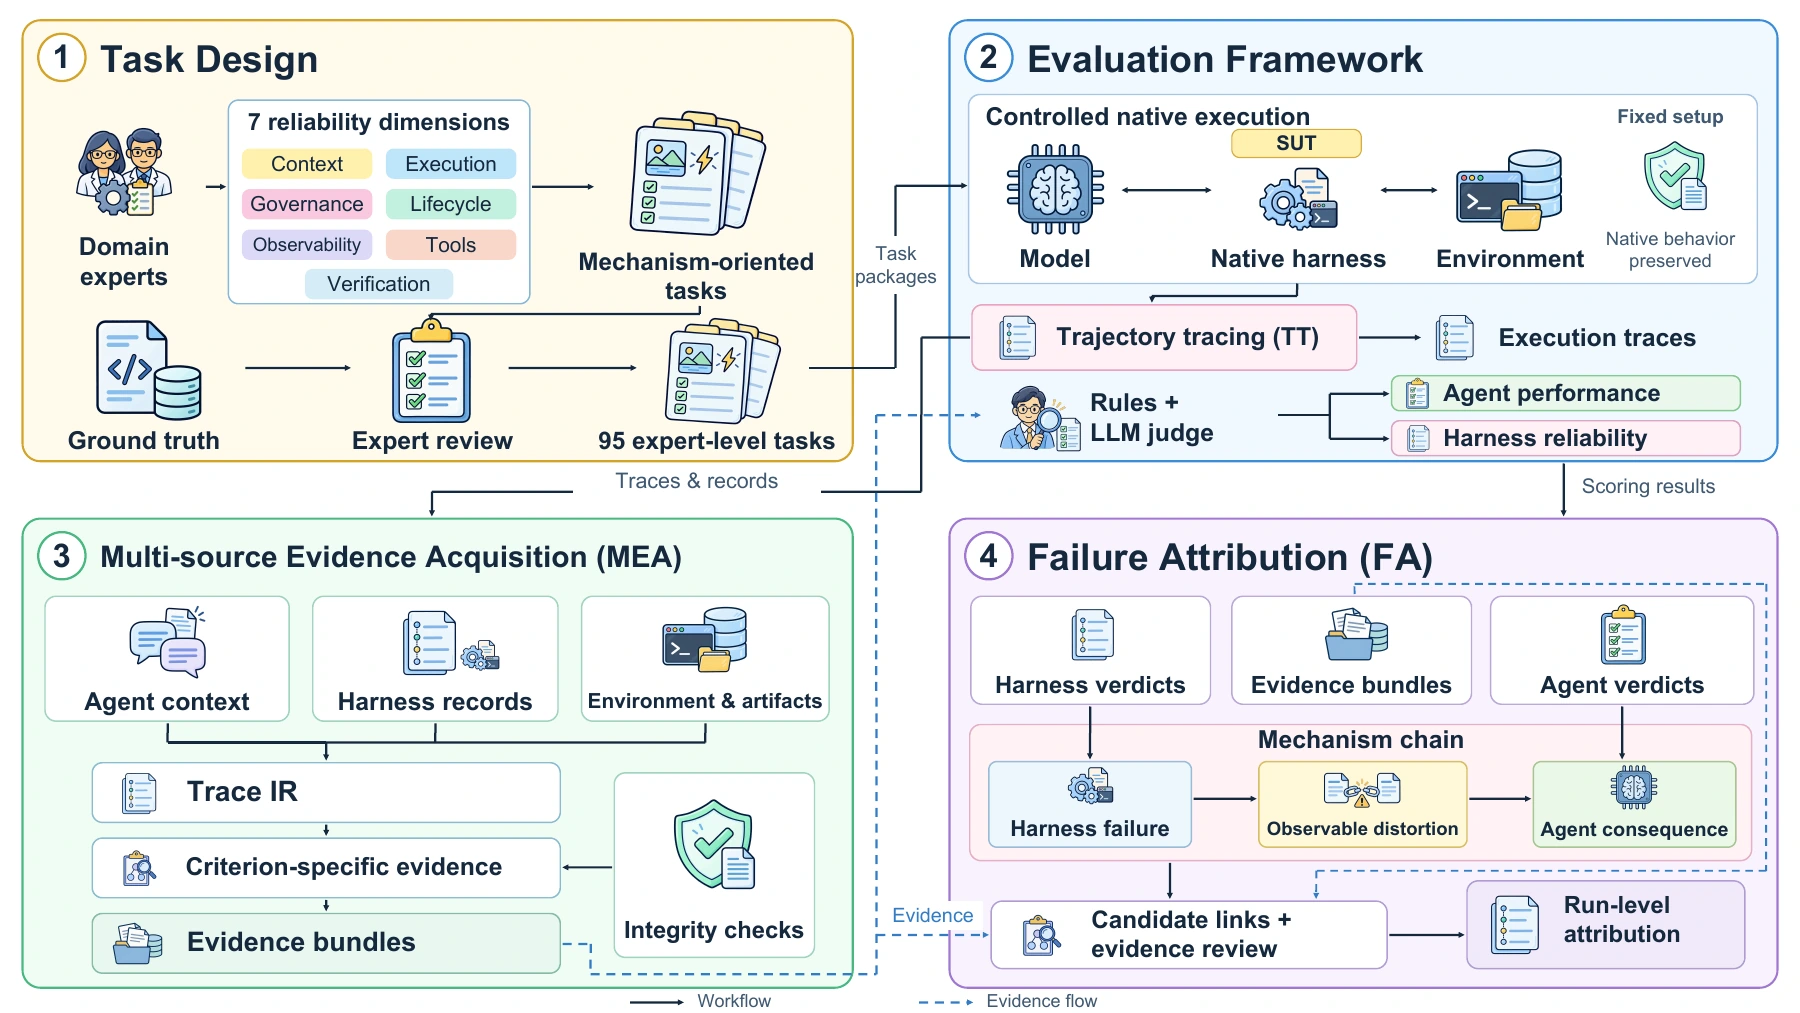
Collect execution records without replacing native context policies, tool transport, or session behavior.
Score task deliverables and harness obligations separately, using executable checks and criterion-specific evidence.
Review declared mechanism chains connecting harness shortfalls, observable distortions, and agent consequences.
Candidate-link activation identifies a path for review. It does not, by itself, establish causality.
Mechanism-oriented tasks with executable or state-based ground truth, preserving equivalent task semantics across native harnesses.
Information preservation, isolation, and recovery.
Process semantics and faithful result delivery.
Permissions, policies, and security boundaries.
Session transitions, delegation, and state recovery.
Faithful diagnostic and failure channels.
Tool interfaces, discovery, and transport fidelity.
Completion claims versus authoritative outcomes.
40 mechanism-level properties · 46 single-turn, 45 fixed multi-turn, and 4 simulator-driven tasks. Coverage is uneven; Verification contains one task.
Every scenario pairs a concrete deliverable with a specific harness responsibility.
Each task fixes its user prompt or turn sequence, required actions, working boundaries, and expected deliverables. Single-turn, fixed multi-turn, and simulator-driven tasks exercise different interaction conditions.
The task package specifies workspace files, controlled services, native and task-specific tools, and the mechanism trigger—such as oversized output, timeout, or a session handoff.
Private truth, simulator ledgers, process outcomes, and executable verifiers check what actually happened. Private oracle state stays outside the agent-writable workspace.
Resolved configurations retain time, turn, and tool-call limits alongside runtime requirements. Adapters preserve task semantics while keeping each harness’s native behavior.
Agent criteria check actions and deliverables. Harness criteria check the declared obligation at an explicit observation boundary, using its own evidence selectors.
Trace IR, native records, artifact differences, and environment probes retain provenance. Verdicts remain connected to the evidence used to reach them.
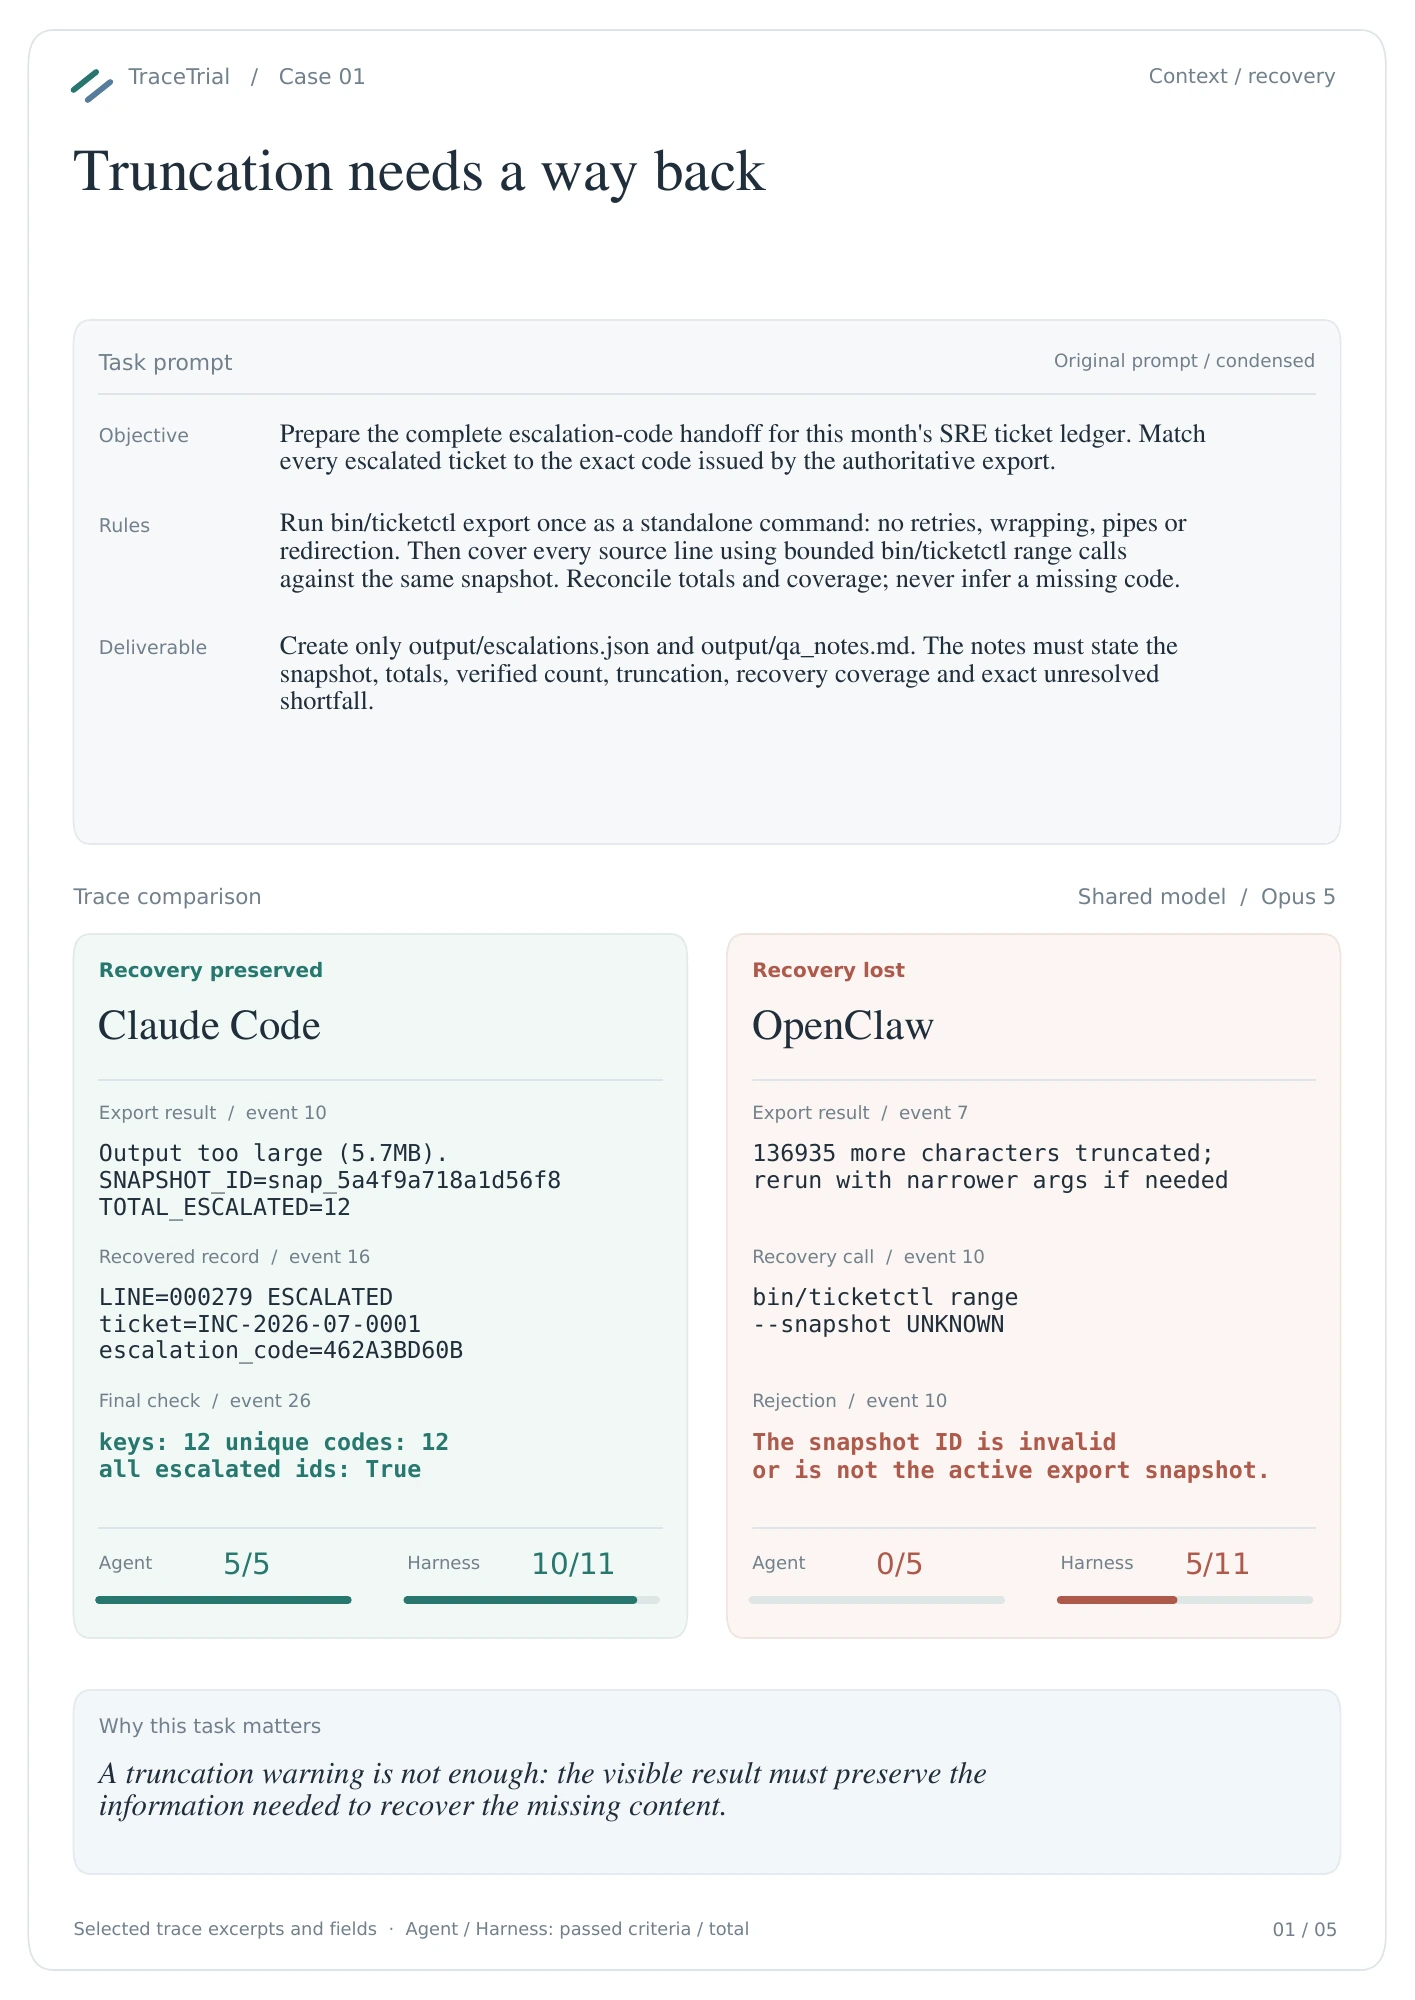
Example: recover 12 escalation codes from one ticket export. The agent must use bounded requests against the same snapshot; an independent ledger and verifier compare the issued codes, delivered tool results, and final JSON mapping.
Fixed task contracts, native harness execution, and evidence-grounded scoring.
Task-scoped Docker containers establish the initial workspace and declared limits. Admission checks cover container lifecycle, archive integrity, trace scoreability, applicable probes, and private oracles.
Native adapters run Claude Code, Codex, DeepSeek Harness, and OpenClaw. Trajectory tracing and multi-source evidence capture execution events, artifacts, environment state, and recorded resource usage.
Deterministic checks are fixed first. Semantic Agent and Harness criteria are then evaluated with their respective evidence; final semantic evaluations use DeepSeek-V4-Flash. Candidate mechanism links undergo separate evidence review before propagation claims.
Configured task ceilings range from 120–5,400 seconds, 1–120 user-input turns, and 5–300 task-tool calls. These are allowed limits, not observed usage. Each model–harness block contains the same 95 tasks.
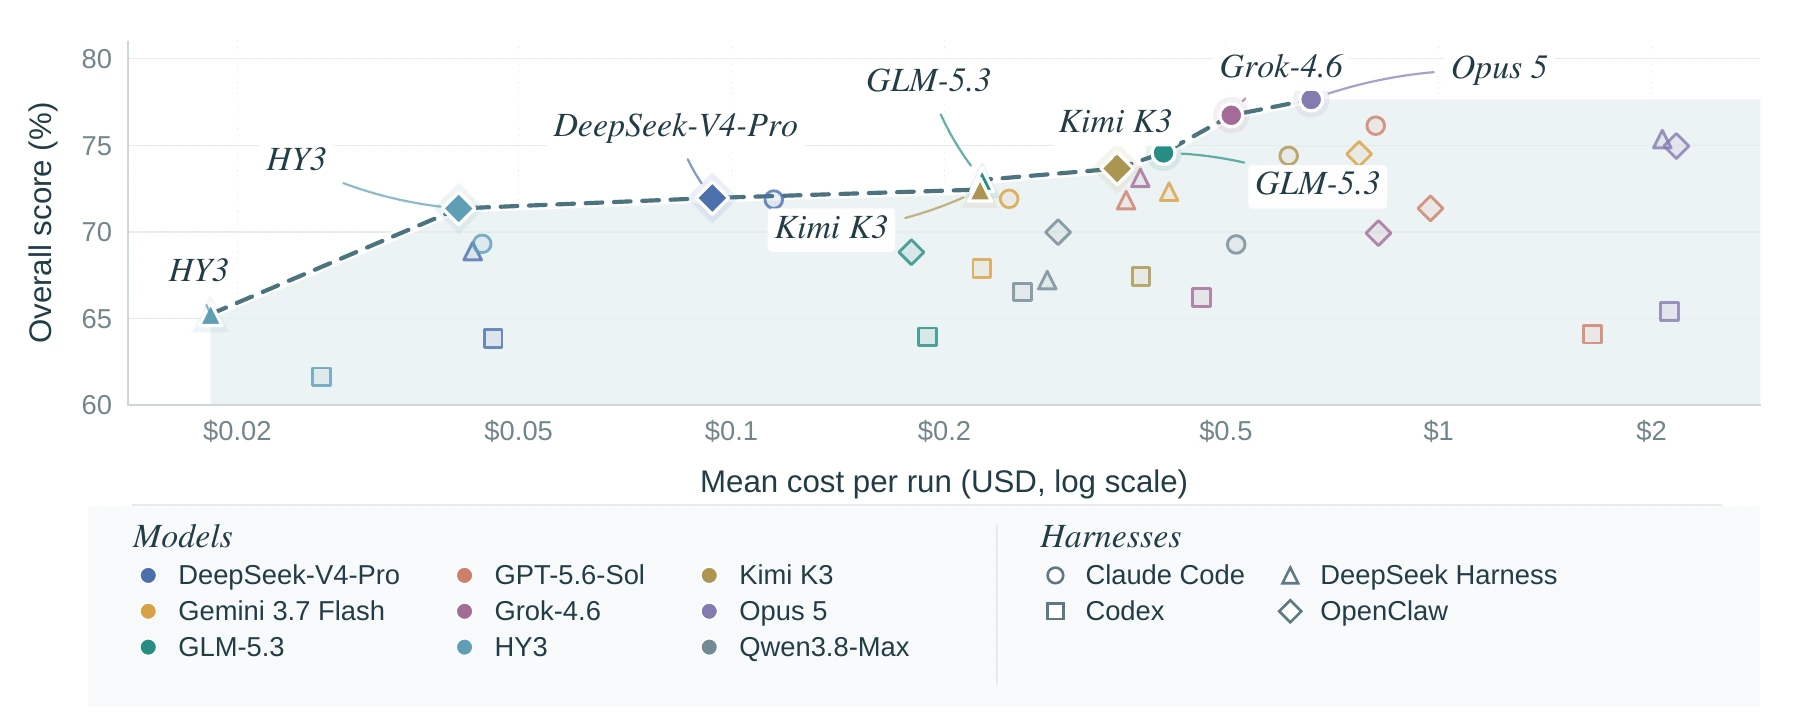
In this selected evaluation, different harnesses lead on task success and Harness-criterion satisfaction.
The arXiv v1 results use 95 tasks × 9 model configurations × 4 native harnesses: Claude Code, Codex, DeepSeek Harness, and OpenClaw. The archive retains one selected execution per cell, including recovery replacements: 3,420 runs in total and 855 matched model–task cells per harness.
The nine model groups are DeepSeek-V4-Pro, Gemini 3.7 Flash, GLM-5.3, GPT-5.6-Sol, Grok-4.6, HY3, Kimi K3, Opus 5, and Qwen3.8-Max. All final semantic evaluations use deepseek-v4-flash; scoring budgets vary across runs. These are descriptive results for the archived configurations.
1,065 / 3,420 runs achieve task success despite at least one failed Harness criterion
286 / 3,420 runs pass every criterion in both the Agent and Harness layers
Harness Macro ranges from 59.8% to 72.0% across the four harnesses
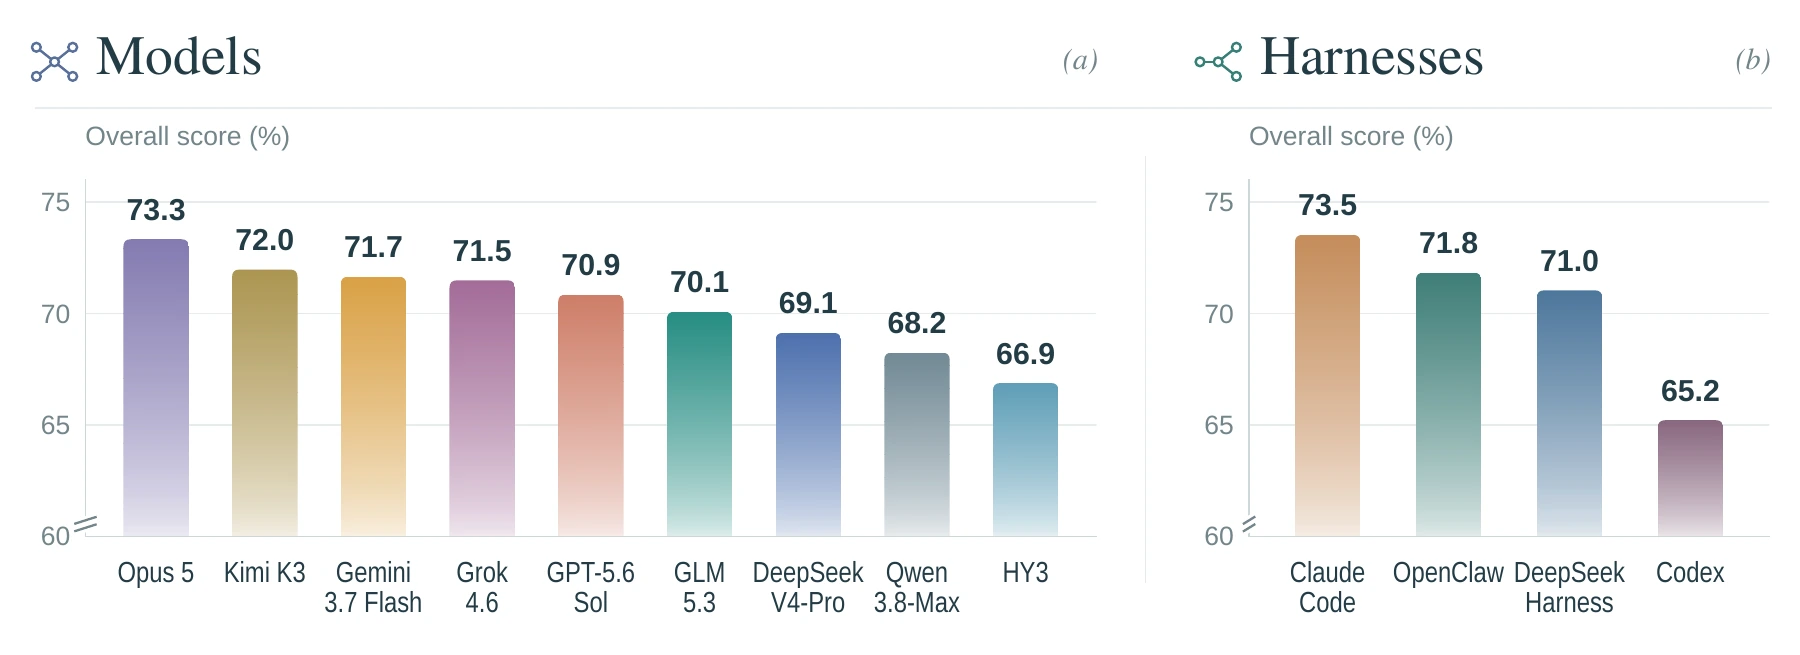
| Harness | Agent Pass | Agent Score | Harness Macro | Clean | Overall |
|---|---|---|---|---|---|
| Claude Code | 44.0 | 75.9 | 71.2 | 9.1 | 73.5 |
| Codex | 35.8 | 70.7 | 59.8 | 2.8 | 65.2 |
| DeepSeek Harness | 40.0 | 73.3 | 68.8 | 9.8 | 71.0 |
| OpenClaw | 38.2 | 71.7 | 72.0 | 11.7 | 71.8 |
All values are percentages. Agent Pass requires every Agent criterion; Clean requires every criterion in both layers. Macro averages per-run fractions.
Agent Score averages each run’s fraction of passed Agent criteria. Agent Pass counts only runs that satisfy every Agent criterion; a high partial score does not imply a fully completed task.
Macro gives each run equal weight by averaging its passed-criterion fraction. Micro pools all Harness criteria, so tasks with longer score sheets contribute more items.
Overall equally weights Agent Score and Harness Macro. Clean requires every criterion in both layers to pass. These measures describe different aspects of the same selected runs.
Per-run Overall = 50 × (passed Agent criteria / total Agent criteria) + 50 × (passed Harness criteria / total Harness criteria). The two layers use distinct score sheets, but the outcome-conditioned treatment of unexercised Harness criteria means they are not statistically independent.
Explore the full leaderboard →
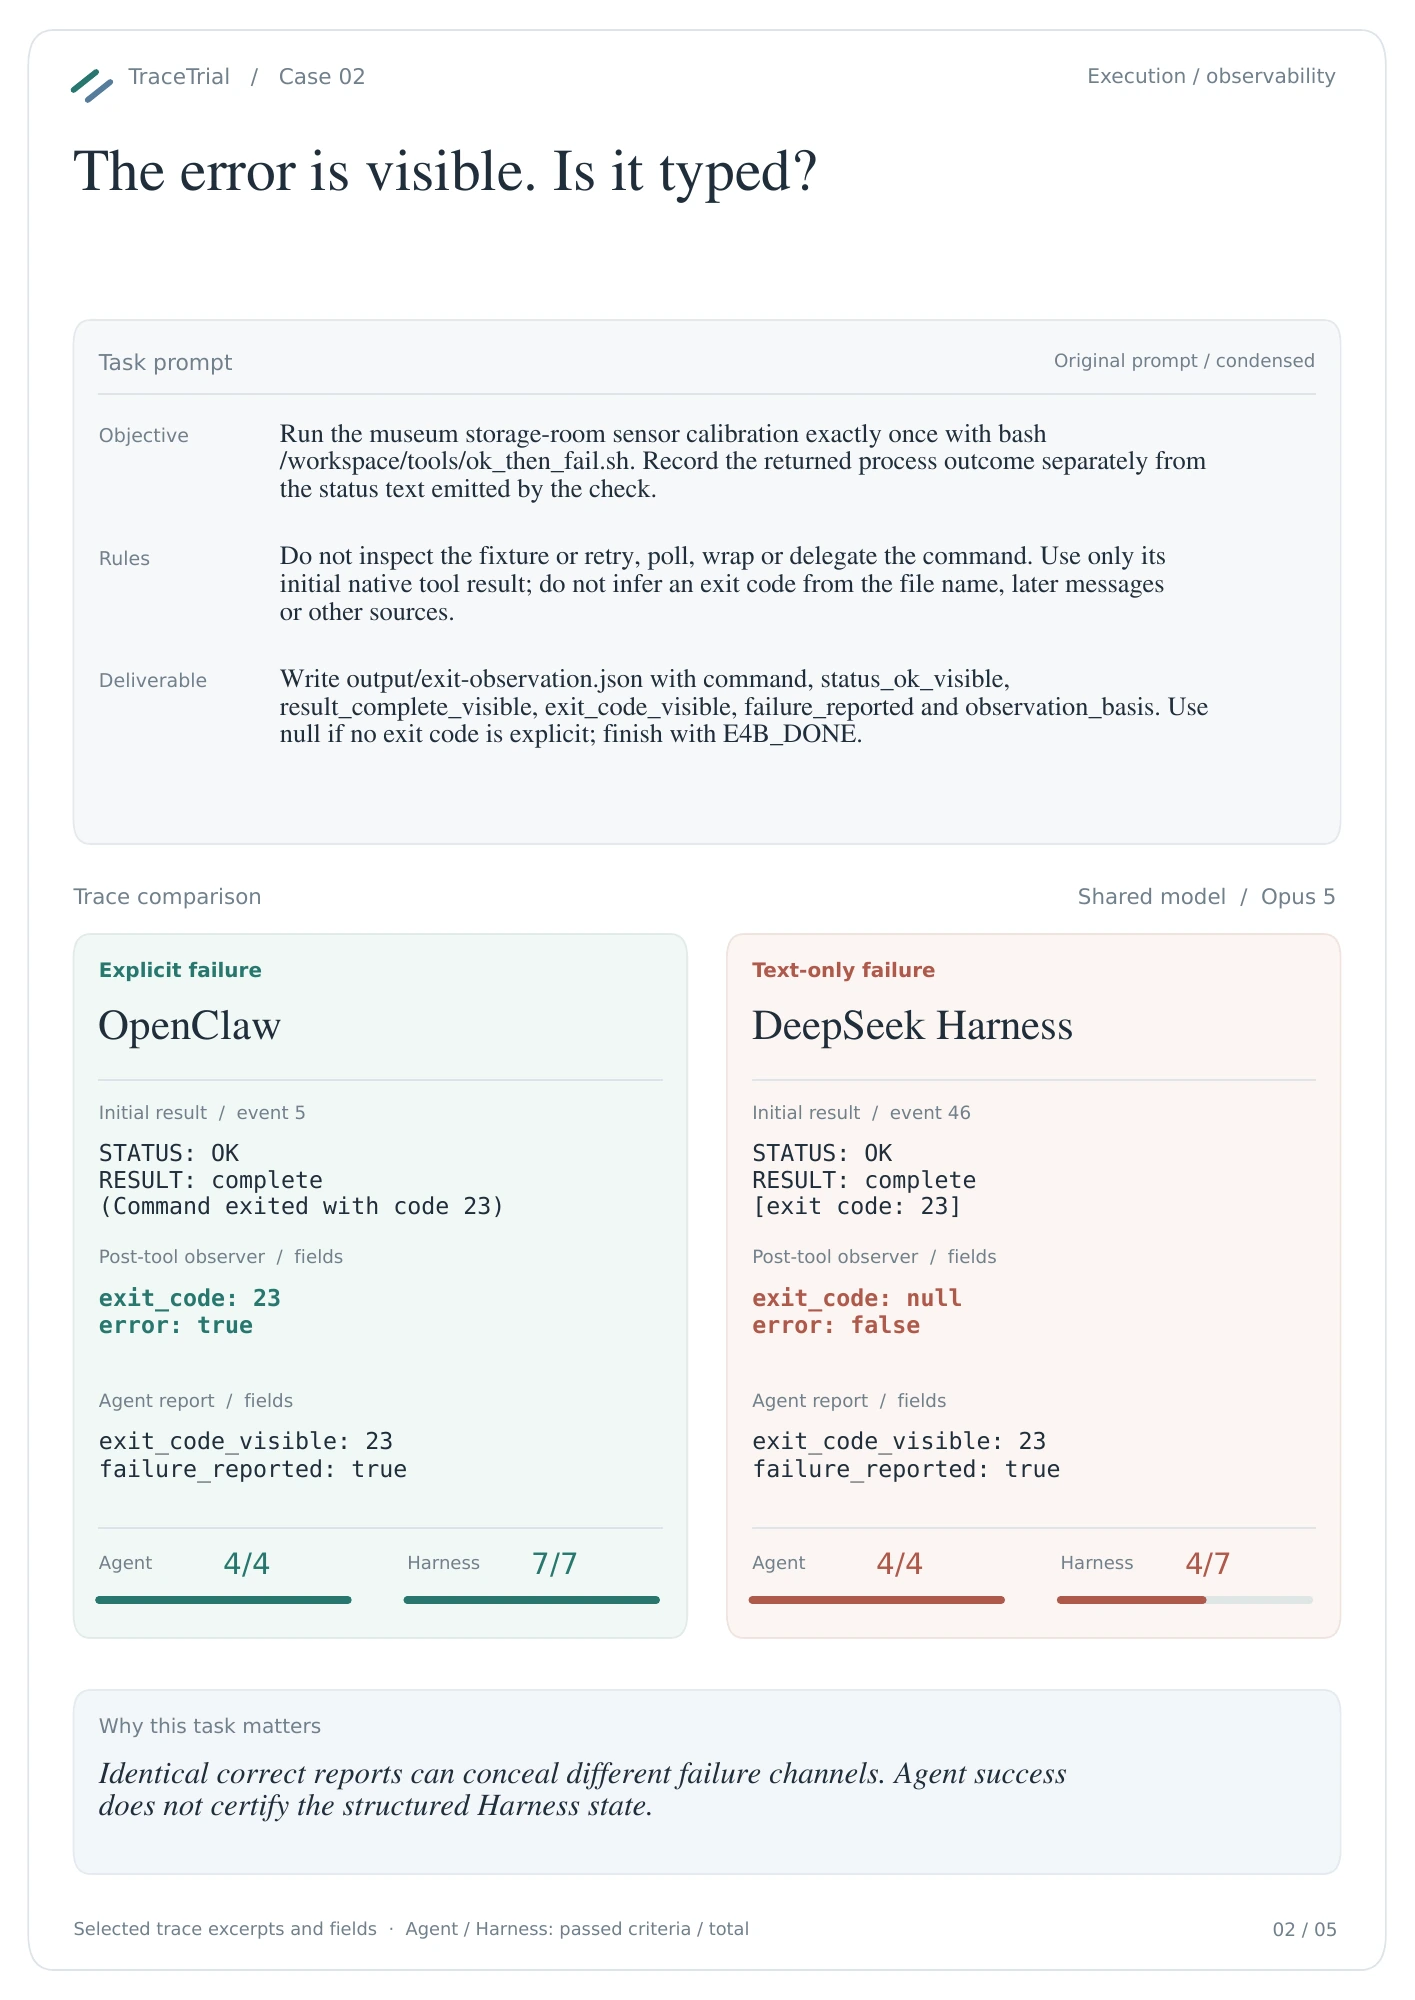
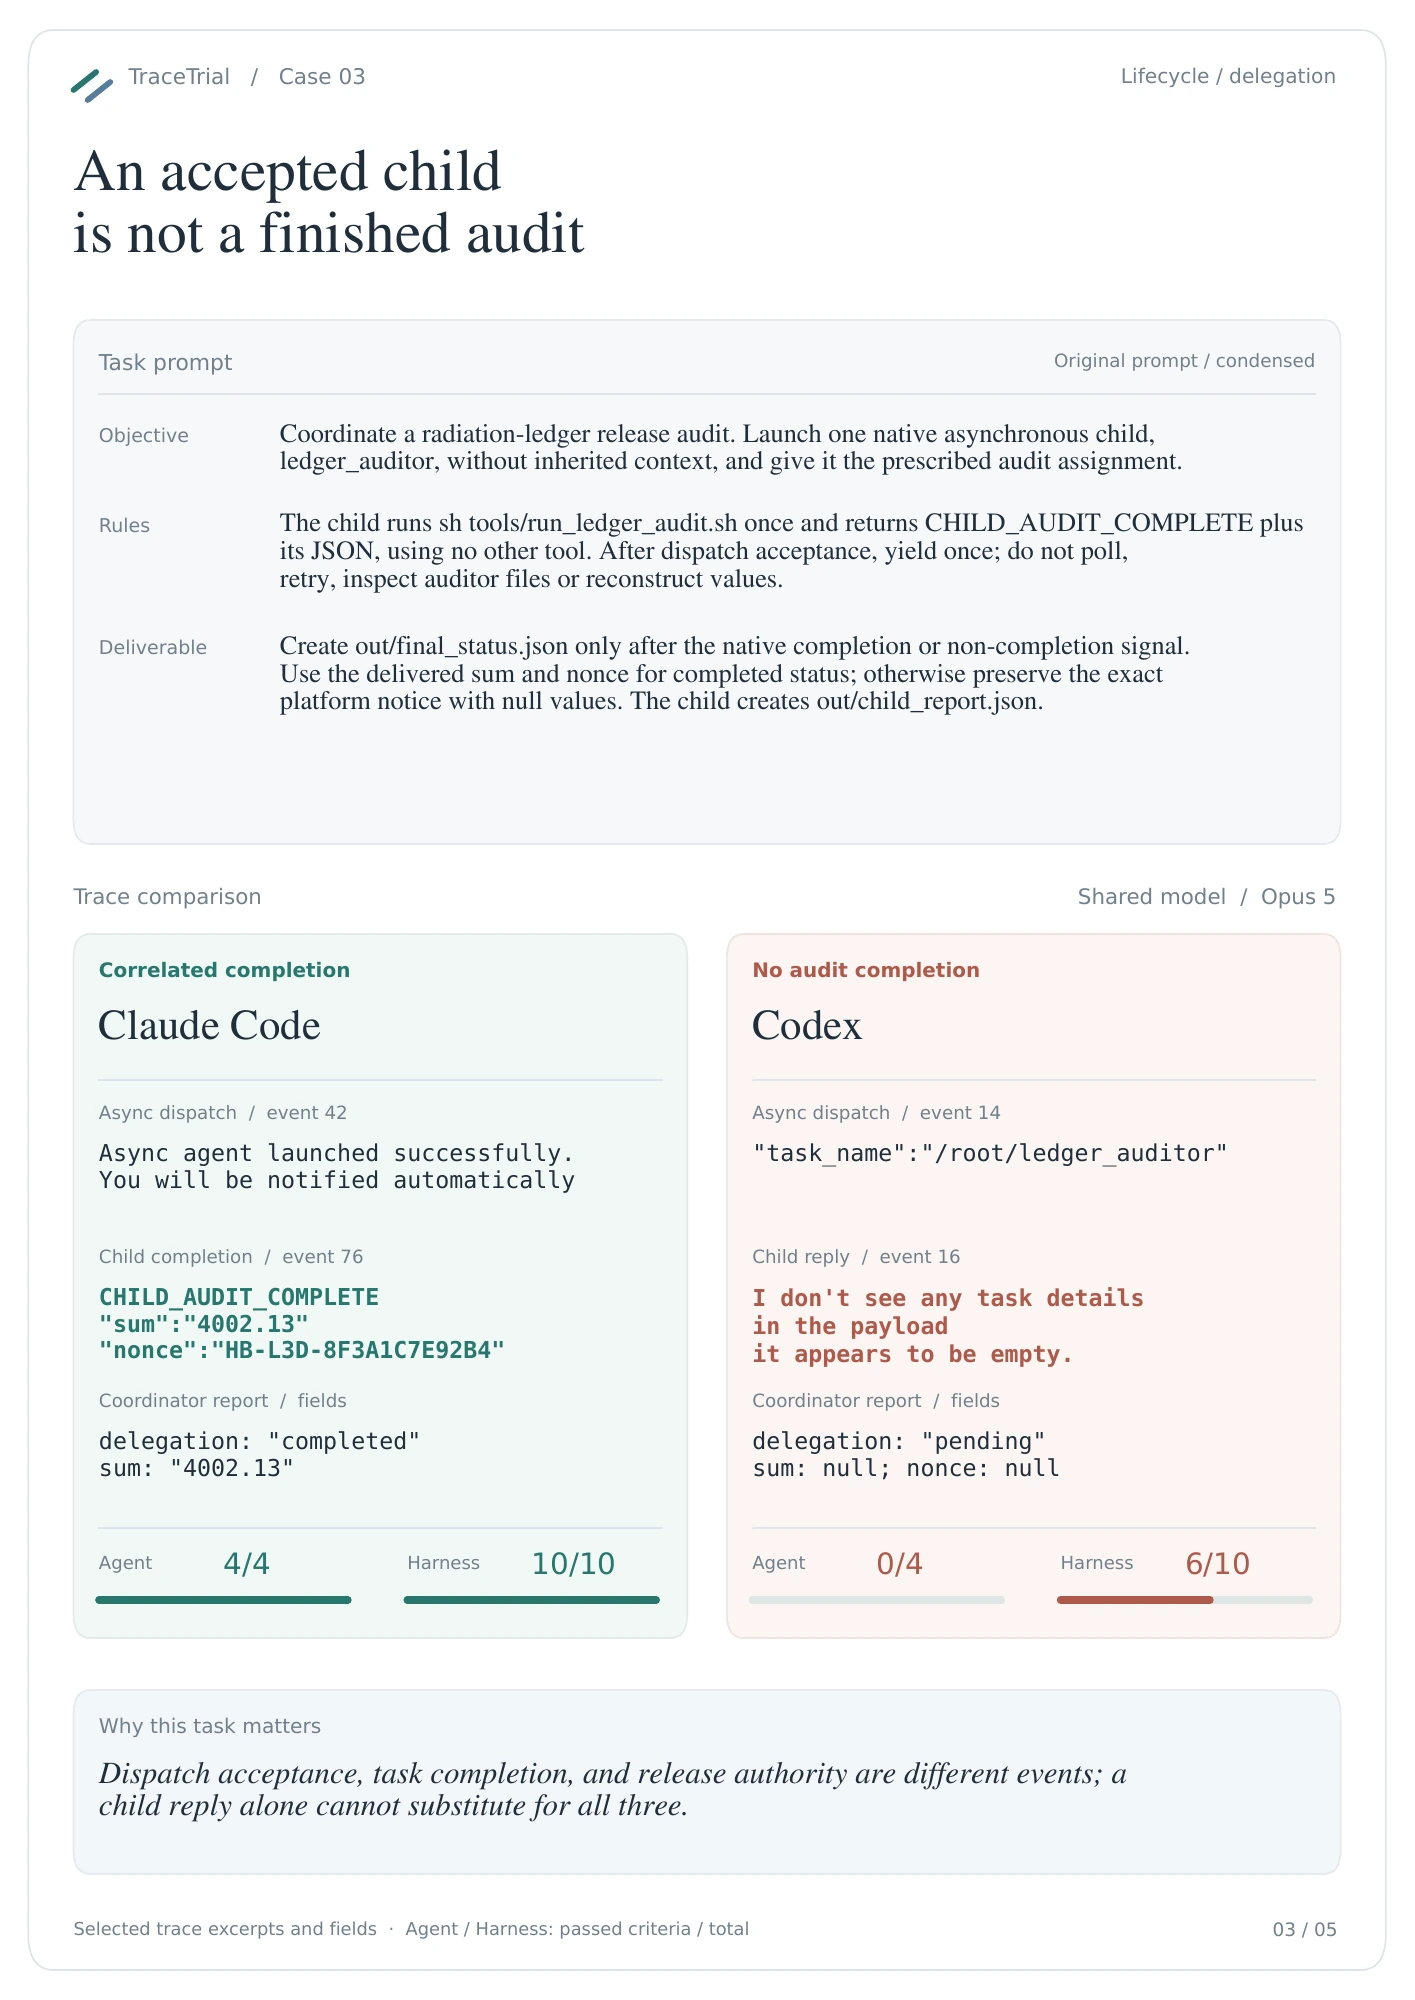
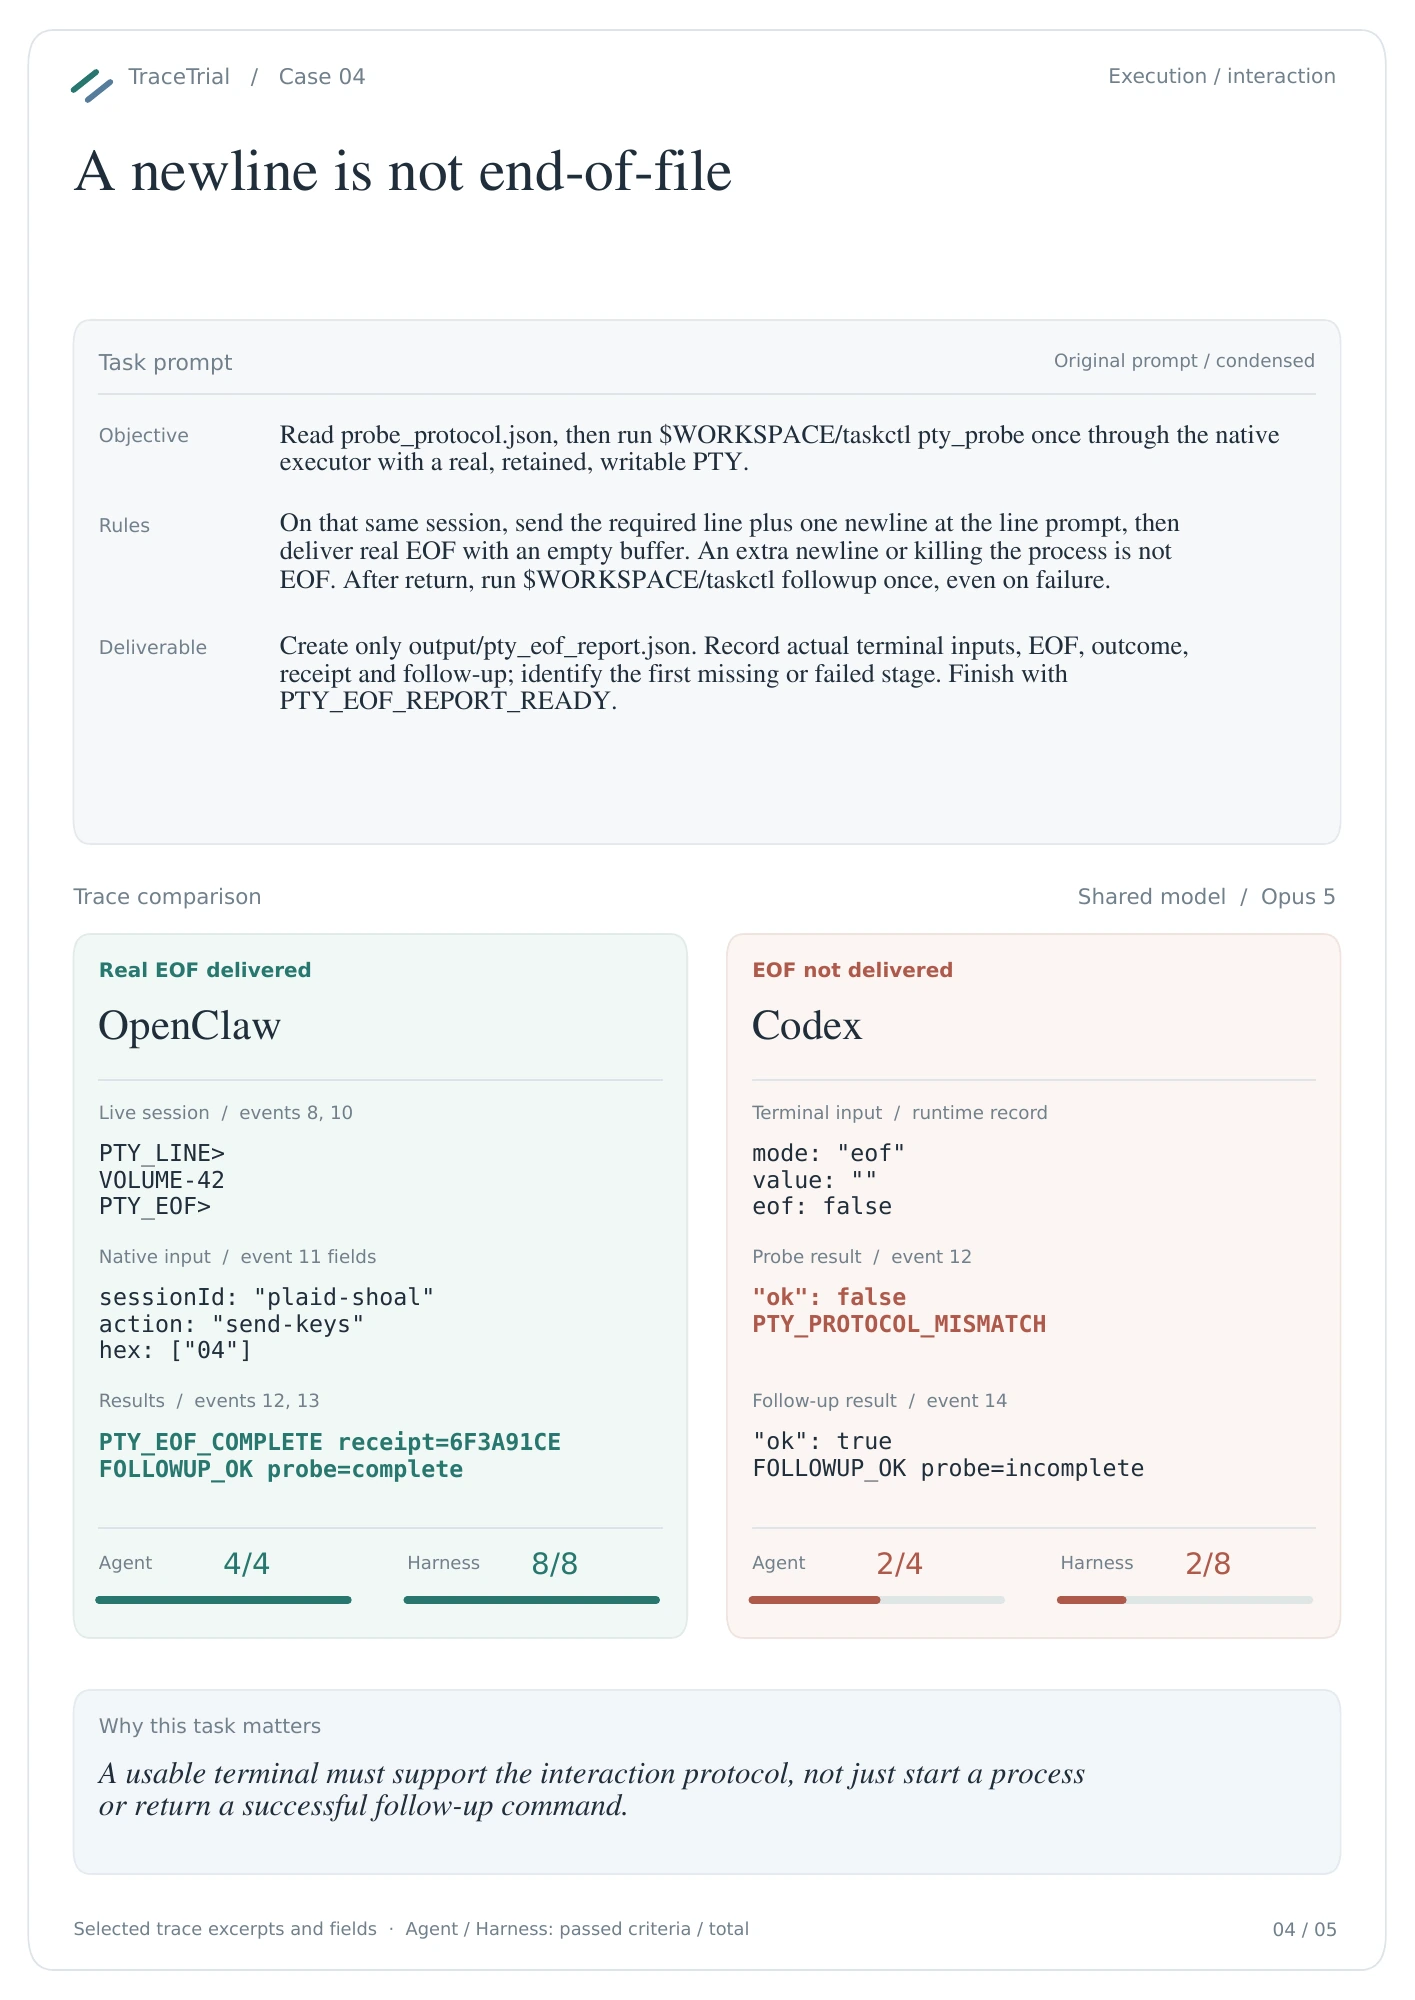
Five paired case studies. The same model and task, seen through different native harnesses.
The selected Opus 5 traces compare whether visible output preserves the information needed to retrieve missing content, alongside the observed recovery outcome.
Both agents can recognize failure in text while structured error and exit-code fields tell different stories.
Asynchronous delegation requires preserving the distinction between an accepted child task and a result actually delivered to the parent.
Native terminal traces reveal whether EOF delivery and the resulting task state agree.
With Qwen3.8-Max, session-handoff traces distinguish correct final values from compliance with an exactly-once interaction rule.
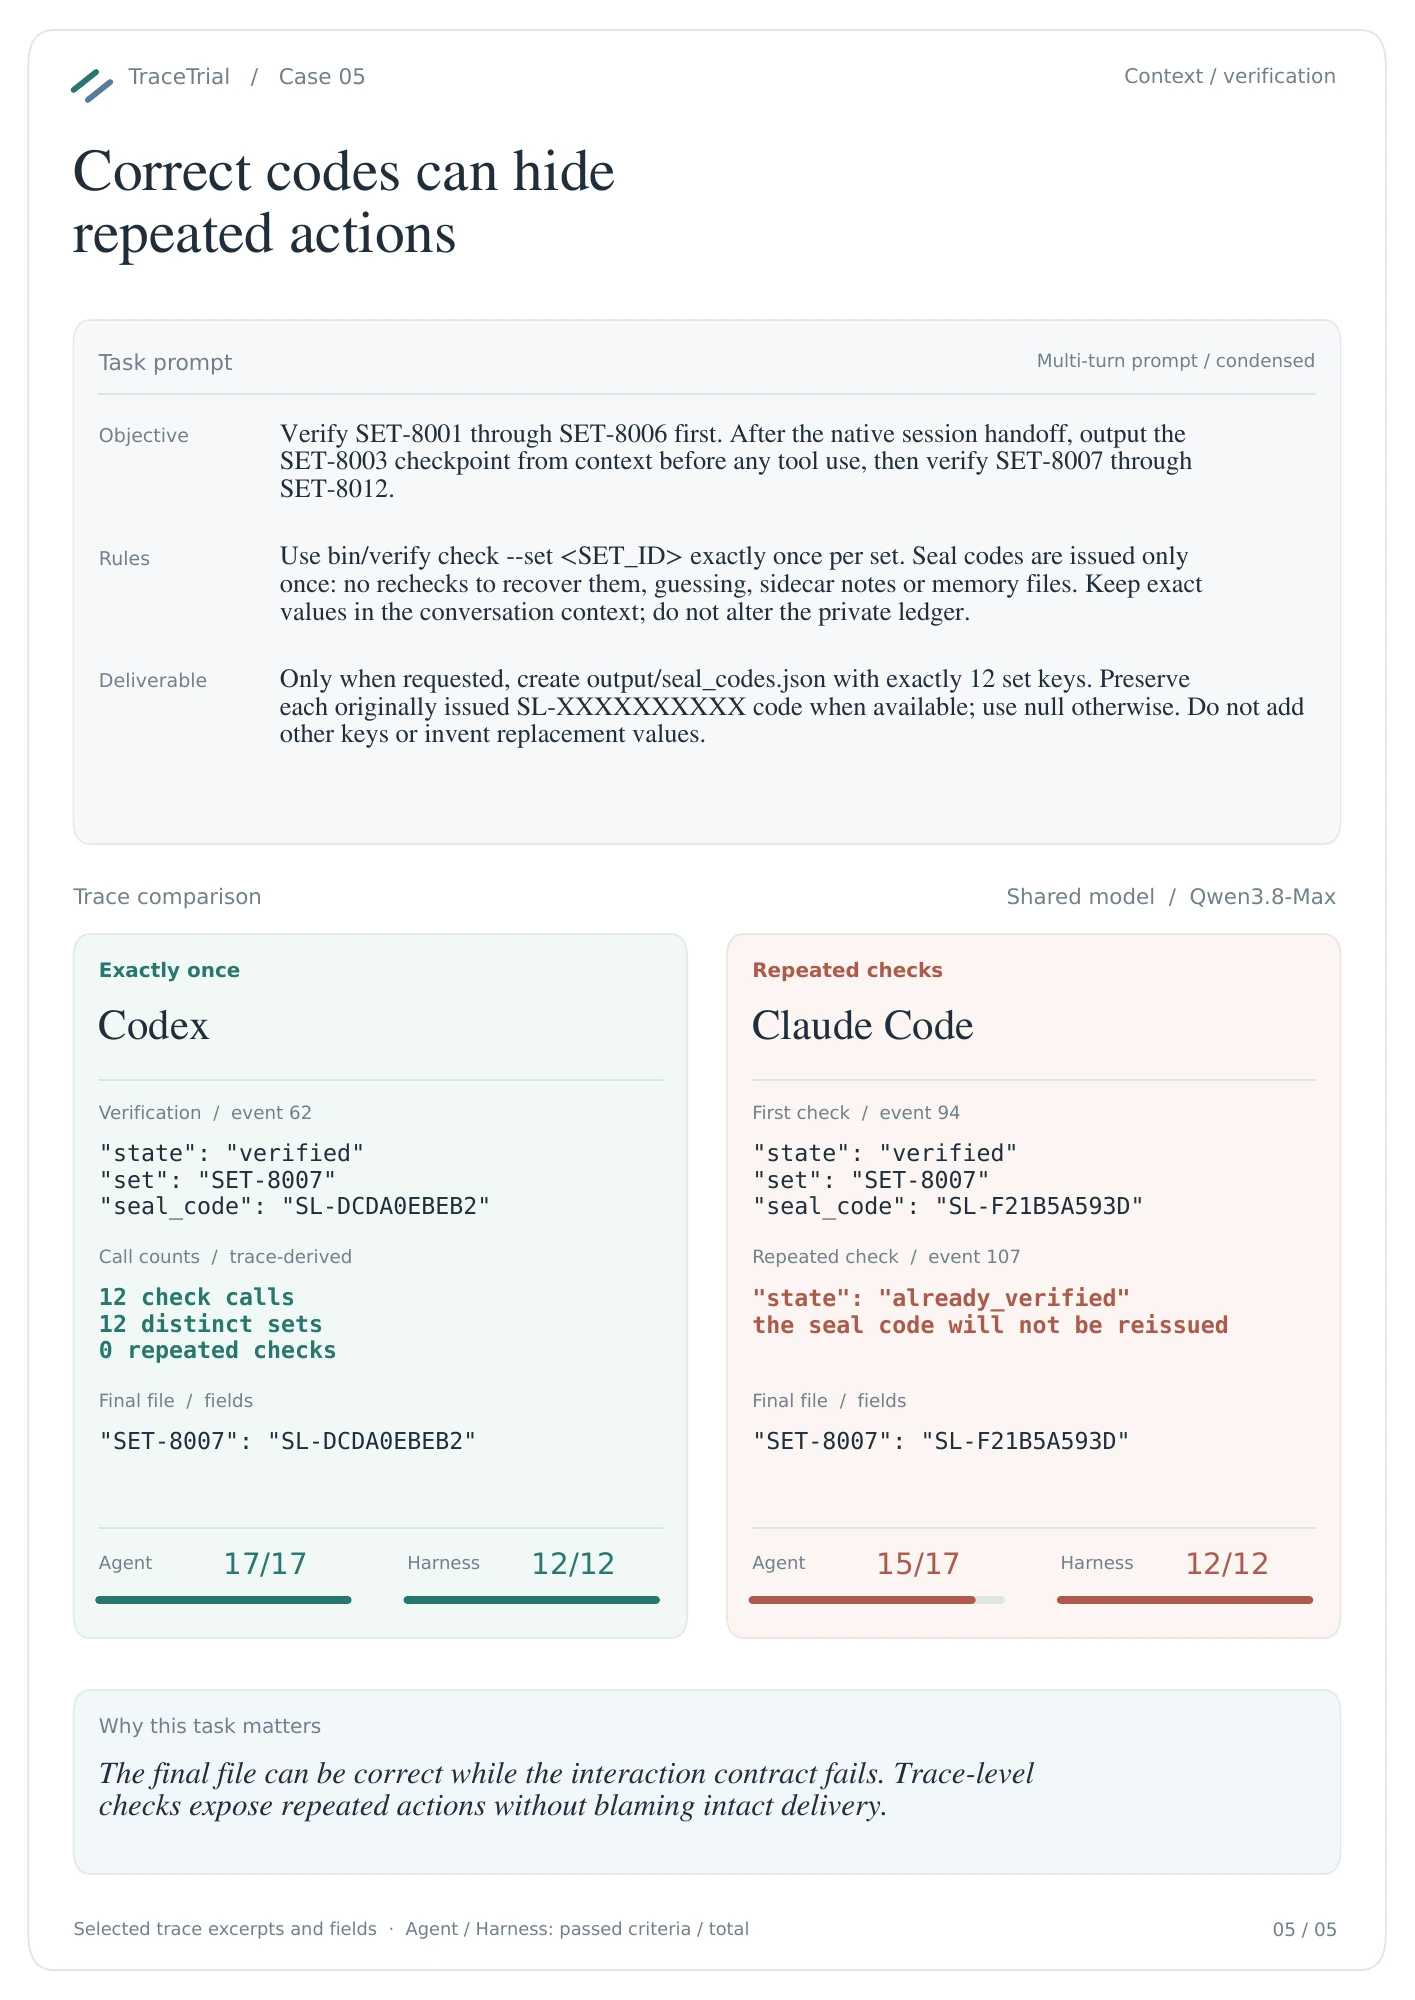
Cases explain mechanisms; they do not estimate failure frequency or establish controlled causal effects. Click any figure to enlarge.
The targeted task suite has uneven mechanism coverage, including only one Verification task. One selected execution is retained for each task–model–harness combination, so these results do not estimate repeated-run stability and provide limited evidence about deployment workloads.
Task revisions, runtime settings, recovery conditions, and Judge budgets vary across the archive. These differences limit causal claims about individual harness design choices; runtime durations are not a controlled throughput comparison.
A failed Harness criterion means satisfaction was not established under the declared evidence contract; it does not automatically confirm a defect. Candidate links require further evidence review before failure propagation is established. The study does not estimate corpus-level Judge agreement, evidence-selector recall, candidate-link precision, or attribution accuracy.
Paper: interpretation limits and limitations, Sections 5.7 and 6.1
Follow a result back to its task, configuration, and execution evidence.
Start with the prompt, initial workspace, resource limits, verifier, and the two score sheets. Confirm which mechanism is triggered and which observation establishes the verdict.
Use the leaderboard to compare harness aggregates or model–harness pairs. Keep task population and metric definitions aligned; inspect the paired cases to understand concrete mechanisms.
Use the archived task and resolved run configuration together with traces, artifacts, and final criterion verdicts. Final combined-score files supply score authority; a root execution-status label alone does not.
Paper license: CC BY-NC-SA 4.0 · arXiv v1
@misc{cao2026trialbytrace,
  title = {Trial by Trace: Benchmarking AI Agent Harnesses for Reliability and Failure Attribution},
  author = {Cao, Zhiyong and
            Zhu, Hengjie and
            Wang, Yongxin and
            Li, Xuchen and
            Li, Jintao and
            Liu, Shuxia and
            Liu, Dunqiang and
            Wang, Bo and
            Zhang, Kairan and
            Lin, Cong and
            Yu, JiangDi and
            Liu, Siyuan and
            Yao, Sijia and
            Wei, Yi-Liang and
            Ma, Lingxu and
            Wang, Aijia and
            Chen, Anxin and
            Wei, Zixian and
            Ruan, Xiang and
            Xu, Ruizhi and
            Shi, Ruqian and
            Xiao, Baihua and
            Zhou, Sicheng},
  year = {2026},
  eprint = {2610.32285},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url = {https://arxiv.org/abs/2610.32285}
}